The Real Cost of an AI-Assisted Fashion Campaign
The correct comparison includes loaded labor, review, correction, tools, production, rights, disclosure, adaptation, and failed outputs—not only the price of a generation subscription.
Start with what’s new. Find the reporting that helps with your next decision.
The correct comparison includes loaded labor, review, correction, tools, production, rights, disclosure, adaptation, and failed outputs—not only the price of a generation subscription.
Synthetic people can expand creative options, but they cannot quietly impersonate documentary photography, customer experience, or product truth.
The apparent savings from generating a person can disappear into correction, product review, rights, consent, labor, disclosure, provenance, accessibility, and customer trust. The person in the image is not a disposable production input.
The answer depends on what “fit intelligence” does, who uses it, which products qualify, how return reasons are captured, and whether conversion, bracketing, margin, customer experience, and completed return windows are measured together.
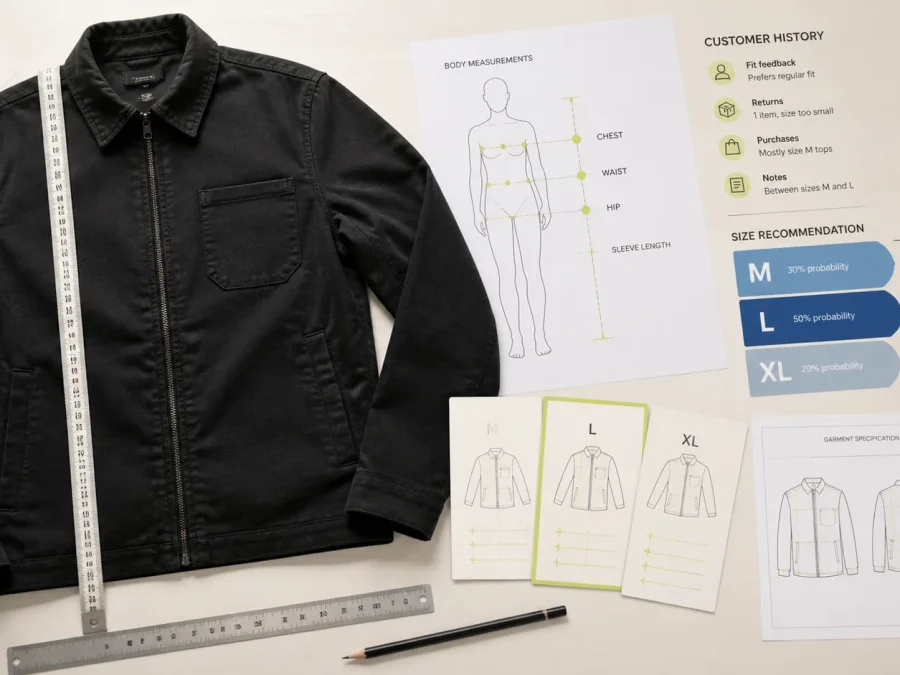
A size recommendation is a probability built from product, customer, and outcome data—not a measurement of objective truth.
Current tools can create useful style visualizations, but a generated image is not a fit guarantee, size recommendation, stock promise, product-fidelity certificate, or return-reduction result.
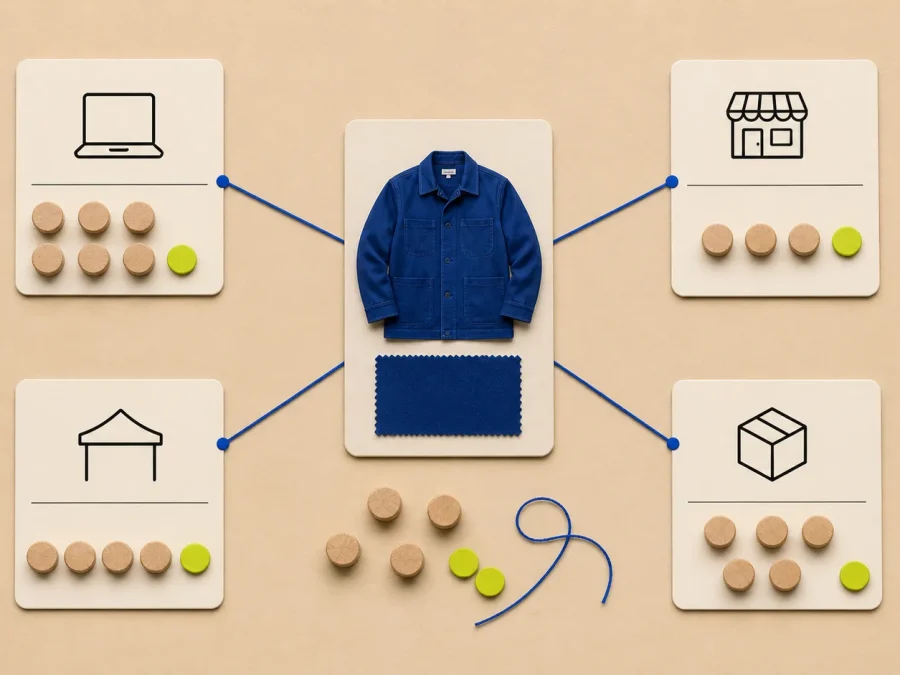
Allocation begins with one trustworthy inventory picture, explicit channel service goals, and a baseline that exposes scarcity. AI can update demand ranges, but it should not hide who loses when stock is short.
Small fashion teams can begin with clean weekly data, a hard-to-beat baseline, honest uncertainty, and a repeatable buying decision.
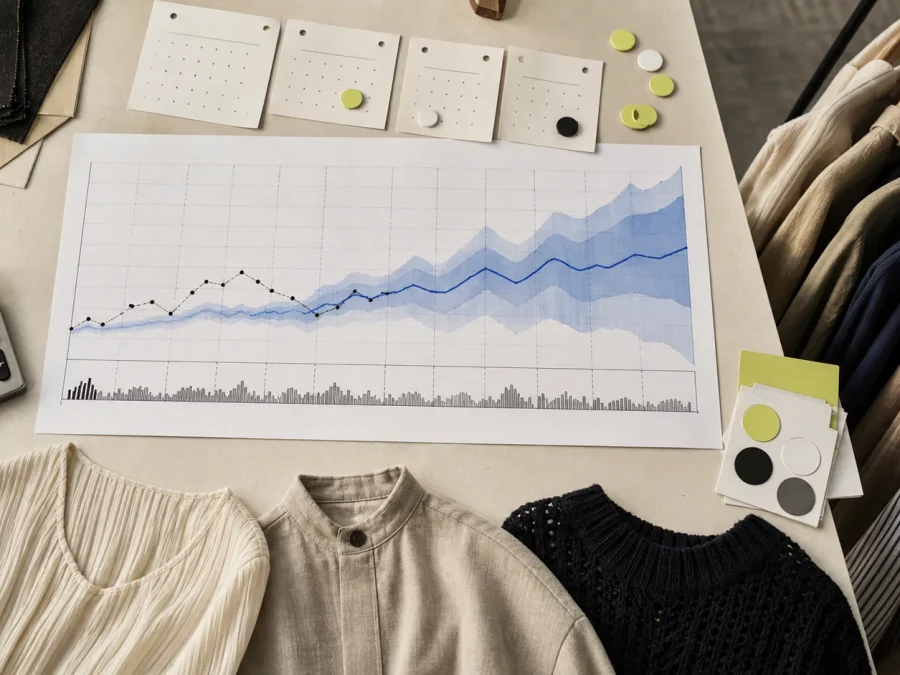
Begin with the buying decision, constraints, and a transparent baseline. Use AI to test demand and substitution assumptions—not to turn uncertain fashion forecasts into an automatic order.
The useful change is not an automatic buy plan. It is a weekly decision record that makes source freshness, forecast versions, exceptions, commercial inputs, ownership, and human approval visible.
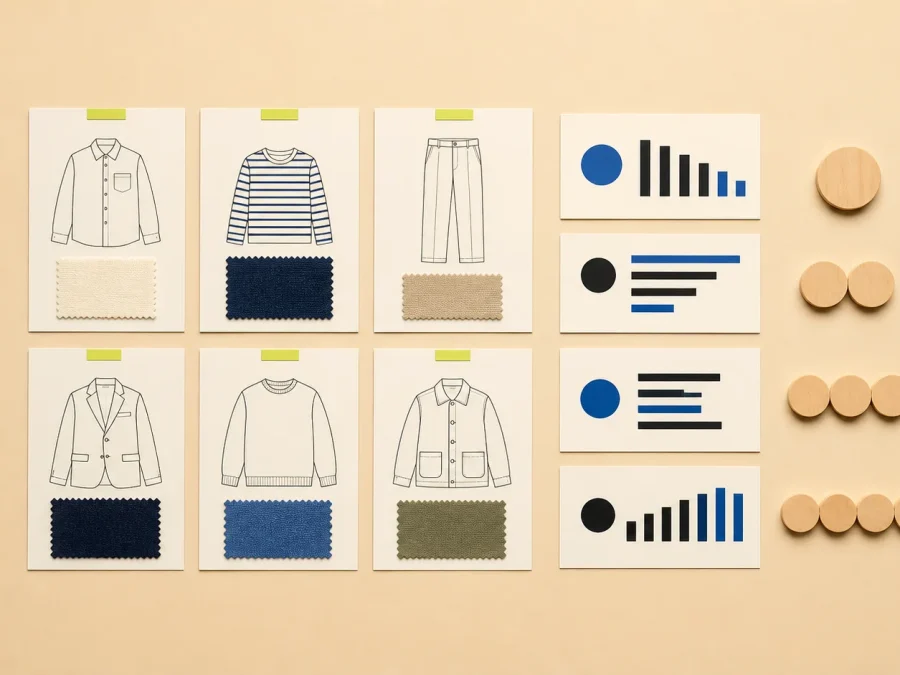
A small catalog does not make recommendation testing simple. Inventory, merchandising intent, sparse interaction data, privacy, accessibility, attribution, returns, and gross margin all belong in the decision.
A fair comparison freezes the catalog, query set, relevance judgments, inventory state, interface, and measurement plan. Until that test is run on an authorized storefront, attractive AI answers are demonstrations—not evidence of better discovery.